LiberAI introduces Liber-0, a world action model pretrained on more than 2.2 million hours of human experience to support zero-shot robot manipulation. In an evaluation of 60 tasks proposed by GPT-6, it achieved 36.0% overall success without robot demonstrations collected specifically for those target tasks. The model combines large-scale human video, glove-recorded hand motion and embodiment alignment to transfer human manipulation experience to robots.
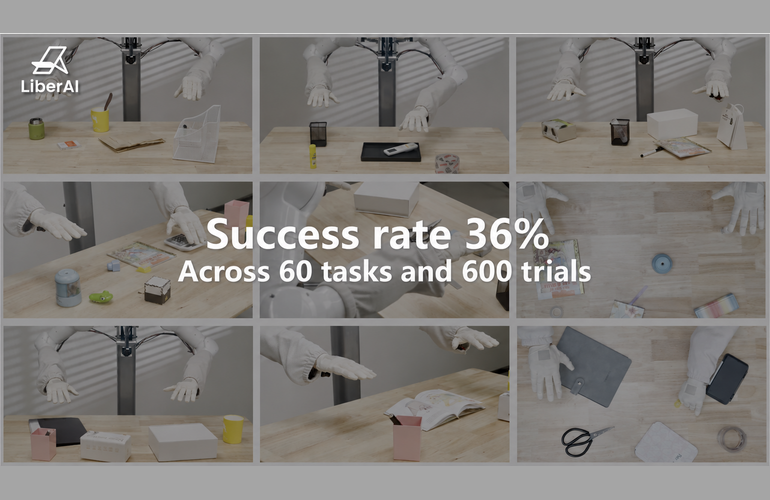
Liber-0 achieves 36.0% overall success in a zero-shot evaluation of 60 tasks proposed by GPT-6.
LiberAI has introduced Liber-0, a world action model (WAM) pretrained on more than 2.2 million hours of human experience. The Beijing-based startup said the model combines human video with glove-recorded motion and embodiment-conditioned learning to transfer human manipulation experience to robots.
A central test of Liber-0’s generalization is whether it can perform target tasks without robot demonstrations collected specifically for them. LiberAI evaluated the model on a separate suite of 60 GPT-6-proposed tasks, distinct from its internal scaling benchmarks: 20 pick-and-place (PnP) tasks, 20 non-PnP manipulation tasks, and 20 challenging non-PnP and long-horizon tasks.
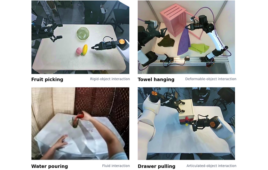
Examples from the suite include placing a pen in a pencil case, pushing a drawer closed, and a longer sequence in which a pen is placed in a pouch and the pouch is stored in a drawer.
LiberAI reported task success rates of 63.5% on pick-and-place tasks, 34.0% on non-pick-and-place manipulation tasks and 10.5% on challenging non-pick-and-place and long-horizon tasks, with an overall success rate of 36.0% across 600 trials.
Here, zero-shot means the evaluated checkpoint was not trained on robot demonstrations collected specifically for these target tasks; pretraining still included robot data.
Why learn from people?
Robot manipulation has traditionally relied heavily on demonstrations recorded on a specific robot for a specific task, usually by a human operator teleoperating the machine. That data closely matches deployment, but collecting it can be slow and expensive, particularly when new tasks or robot platforms require additional demonstrations. Human activity is far more abundant, and much of it is already on video.
The obstacle, according to LiberAI, is that human video does not translate directly into robot commands. Cameras sit in different places, hand poses estimated from video are noisy, and human bodies move differently from robots.
Liber-0 connects human experience with robot action in three ways. First, LiberSense Glove, LiberAI’s data-collection system, directly records hand movements, helping link human video to the motions behind it. Second, LiberAI’s robot platform uses camera views and hand, wrist and waist movements that more closely match those of humans, making skills easier to transfer. Third, a Unified Embodiment Representation gives the model information about body shape and joint movement, so it can adapt actions to the body performing them.
Liber-0 jointly predicts future video frames and actions. This lets it learn from ordinary videos without action labels alongside glove and robot recordings that include measured motion.
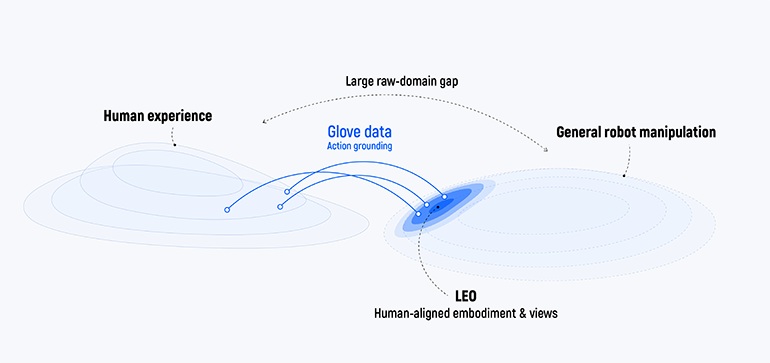
Human-to-robot transfer. Conceptual illustration of how action-grounded human recordings and visual and kinematic alignment support transfer to LEO.
Learning actions that robot data lacked
Glove data can also introduce behaviors missing from a policy’s robot data. LiberAI trained policies whose robot demonstrations covered only pick-and-place, while glove demonstrations included actions such as folding, pressing and opening. Performance was measured as a progress score, a 0 to 100 measure that credits partial completion, across four pick-and-place and six non-PnP tasks. With robot data alone, the non-PnP progress score was 2.2. Adding glove recordings of those actions raised it to 47.5, and to 54.6 when the glove set also included pick-and-place, close to the 56.3 scored by a policy trained on robot demonstrations of every action. This controlled experiment is separate from the 60-task suite: the actions appeared in the glove demonstrations but not in the policies’ robot demonstrations.
A quarter of the robot data
A separate experiment examines whether glove recordings can reduce the need for robot demonstrations. In an eight-task evaluation on LiberAI’s robot platform, where the full robot and glove pools contained equal numbers of demonstrations, a policy trained on 25% of the robot pool plus 100% of the glove pool reached a progress score of 75.6. A policy trained on 100% of the robot pool scored 72.8.
In that setting, glove recordings delivered comparable performance with 75% fewer robot demonstrations. The saving applies to robot demonstrations specifically, as the mixed policy still drew on the full glove pool. Because glove collection does not require a robot at each site, LiberAI says experience can be gathered from more people, in more places, and potentially at lower cost.
Evaluating the pretrained model directly
On LiberAI’s internal benchmarks, the pretrained checkpoint achieved progress scores of 81.4 on pick-and-place and 72.3 on non-PnP tasks when evaluated directly. Robot post-training added 2.2 and 1.5 points, to 83.6 and 73.8. LiberAI said the small gain indicates the pretrained model already captures much of the capability needed for the evaluated tasks.
LiberAI has developed an interactive simulation in which users can upload their own objects and watch Liber-0 manipulate them in a virtual environment. The simulation demonstrates object-level generalization: that version of the model was post-trained on 100 hours of simulated teleoperation data and receives no further object-specific training.
“Human video shows what people do, but not exactly how their hands move or how that movement fits a different body,” said Songming Liu, founder and CEO of LiberAI. “Grounding that experience in measured motion and aligning it with the robot’s body is what turns it into robot capability.”
Introducing Liber-0, our World Action Model for zero-shot robot manipulation—including dexterous, multi-step tasks.
Across 60 tasks proposed by GPT-6 and 600 trials, Liber-0 achieved 36% overall success without robot demonstrations collected specifically for those tasks:
• Pick-and-place: 63.5%
• Other manipulation tasks: 34.0%
• Challenging multi-step tasks: 10.5%Zero-shot capability extends beyond individual actions to coordinated sequences.
Pretrained on 2.2M+ hours of human experience, Liber-0 jointly predicts future observations and actions to turn human experience into robot skills.
Technical blog: https://t.co/X5NMTjsr8r
— LiberAI (@liberai_robot) November 4, 2026
What’s next for LiberAI
LiberAI noted that LiberSense Glove currently records hand poses and trajectories but not contact or force, which matter for insertion, fastening and handling soft materials. Tactile and force sensing, alongside data collection across a wider range of homes, remain future research directions.
Watch Liber-0 in action and explore the full evaluation on LiberAI. For collaboration on models, robotics, LiberSense Glove or other opportunities, contact the LiberAI team via the website.
Sponsored content by LiberAI
Tell Us What You Think!